SSPs and Ad Exchanges Built for AI App Publishers
Conversational ads need infrastructure designed for dynamic intent, not static page slots.
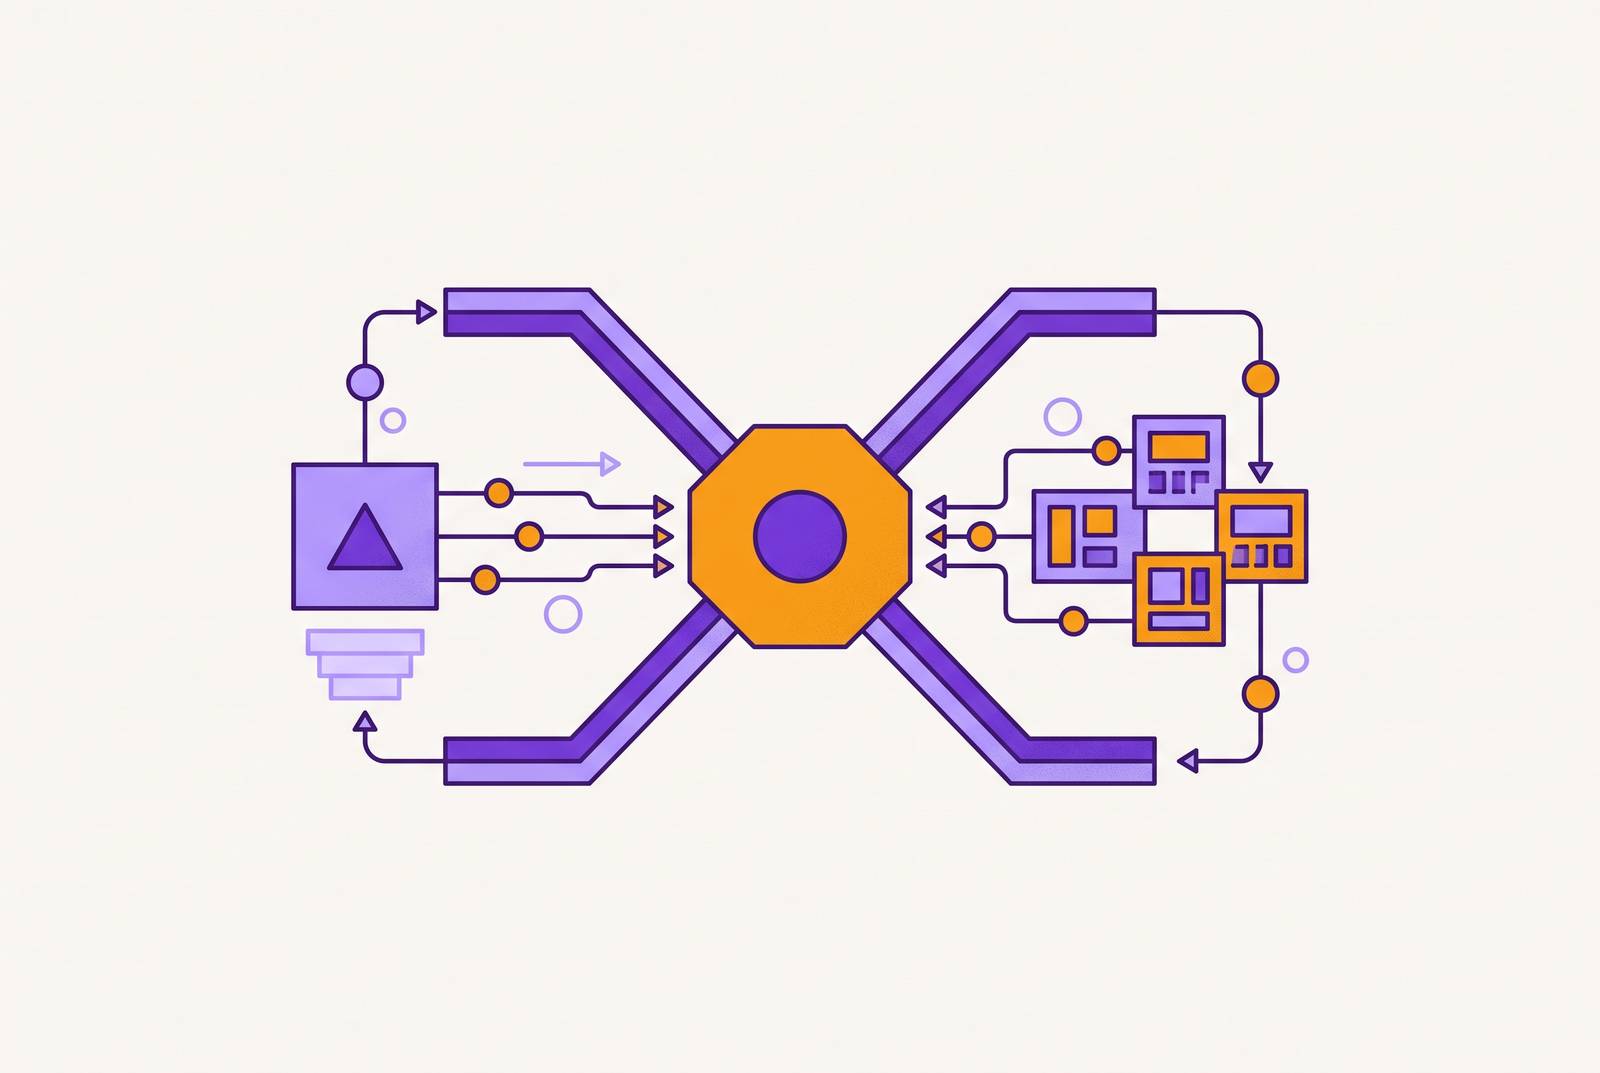
AI app publishers need monetization infrastructure built around generated responses. Purpose-built SSPs and ad exchanges must package prompt-level intent, price changing conversational context, enforce suitability during generation, and connect publishers to context-aware demand. Thrad operates in this category with an SSP and exchange built around conversational context.
Why legacy SSP infrastructure cannot serve conversational AI publishers
A slot on a page has a place and a format before a reader arrives. A publisher can make that space available, set a floor price, and decide which demand partners may bid. Legacy SSP machinery rests on that stable unit, including bid requests, fill rate, frequency capping, and header bidding configuration. The machinery assumes that the inventory exists before the interaction that makes it valuable.
A conversational AI response reverses that sequence. The user’s prompt determines the answer’s length, topic, and intent, so the commercial opportunity emerges at generation time. Two answers cannot be treated as interchangeable simply because the same app produced them. Static floor prices are therefore too blunt for inventory whose value to advertisers changes with every exchange. This is an architectural mismatch in the inventory definition, data model, and auction trigger that an update cannot close.
What conversational AI interfaces actually produce as inventory
The inventory unit is a generated answer that belongs to an ongoing conversation. An early query such as “what should I pack for Japan in March” carries awareness-level intent. A later query in the same session, “which luggage brand holds up in overhead bins”, carries purchase-level intent. The user and session remain the same, but the commercial moment changes.
The prompt also conveys more than an isolated keyword. “I need to plan a two-week trip to Japan with my family” expresses destination, duration, group composition, and planning stage together. Purpose-built platforms, including Thrad, use the prompt as the main intent signal and package that context for auctions built to handle multi-turn conversations. Preserving those distinctions makes the inventory understandable to buyers.
This inventory definition does not mean an advertiser must influence the answer itself. ChatGPT ads appear below the completed response in tinted boxes that stand out and are clearly labeled, without changing the AI’s answer. The commercial unit sits within the conversation interface, while its relevance comes from the exchange that produced it. Because that context is generated rather than fixed, quality assessment must happen as the output is produced or before generation completes.
How auction mechanics break when applied to answer environments
A legacy programmatic auction begins when a page loads and an SSP sends page-level and user-level signals to buyers. A conversational auction needs a different trigger because the commercial opportunity depends on what the user is trying to accomplish at that turn. Its targeting control is a context hint, a natural-language description of the conversations where an ad belongs. The system must match that description against the live thread.
A relevance-weighted, second-price auction evaluates the context hint, ad title and copy, landing page, and live conversation, with user-level personalization signals when enabled. Relevance can beat a higher bid, so clearing a floor is not enough to determine placement. Semantic fit is also part of the auction logic that Thrad’s exchange was architected to handle from the ground up.
Research on advertisement auctions in retrieval-augmented generation environments looks at how relevance and bids together should decide which ads get placed. The research reflects a distinct constraint, which is that commercial value must be considered together with answer quality. It is evidence of a new auction problem. Attribution is also hard because follow-up questions and delayed conversions go beyond the impression-and-click events that legacy reporting was built to track.
What publisher monetization looks like today, and where the infrastructure gap shows up in practice
Perplexity’s publisher revenue share program is one way for publishers to earn money within AI services. It is a revenue-sharing arrangement rather than an open auction with publisher floor prices, demand partner management, and programmatic yield optimization. OpenAI has pursued multi-year content licensing deals with Dotdash Meredith, Condé Nast, the Financial Times, and others. Those deals include training rights and payments that change based on how often content appears.
These arrangements matter, but they address different economic relationships from the one facing an AI app publisher selling native conversational inventory. A content agreement pays for the rights to content and its use, while an SSP packages and sells chances to show ads. Neither a licensing deal nor a publisher revenue share program gives an app all the auction infrastructure it needs. The distinction is between earning revenue through a platform agreement and managing the yield of inventory.
The missing layer is a mature, standardized way to package conversational supply, communicate its value, run competitive auctions, and enforce response-level quality. Publishers need demand sources to compete with each other to find the clearing price of high-intent moments. That limits systematic yield optimization even when monetization is already happening. The infrastructure gap is therefore a pricing problem as well as an integration problem.
The five things purpose-built supply infrastructure for AI publishers must do that legacy SSPs cannot
The first capability is prompt-level intent packaging. A bid request must carry a structured account of the conversation’s subject and the user’s decision stage, rather than substitute a page URL or demographic segment. That representation makes the opportunity legible to demand. Without it, buyers cannot distinguish an exploratory travel question from a purchase-oriented luggage comparison. The supply layer must preserve the signal that gives conversational inventory its commercial value.
The second capability is dynamic inventory definition. Instead of declaring a fixed placement such as “300x250 slot on article page”, the publisher must be able to define a context class such as “finance queries at comparison stage”. An auction can then be triggered when a generated response matches that class. Floor prices must follow context and intent stage so that a purchase-stage response is not priced as a general awareness exchange. The recurring unit becomes a class of commercial moments.
The third capability is quality enforcement at generation time. A page-category block cannot assess content that has not yet been produced. The supply layer must evaluate the response or the conversation leading to it for topic sensitivity, suitability signals, and category exclusions at the moment of generation, before an ad appears. Its importance grows when users disclose personal concerns to an assistant they treat as a trusted advisor.
The fourth capability is conversation-aware auction logic. The engine must evaluate both how well an ad’s context hint matches the live exchange and whether its bid clears a floor. It must also respond when the thread moves from research to comparison or decision. Intent at turn three may differ materially from intent at turn one. Consequently, both the auction trigger and the allocation decision must be sensitive to the conversation’s direction.
The fifth thing it needs is cross-surface demand aggregation. A publisher with a single AI app and thin single-source demand needs to reach advertisers who buy across multiple AI surfaces. An exchange above individual publisher supply can create competition that a direct deal cannot. Broad programmatic reach without conversational signals provides access to buyers, while a single-surface arrangement preserves context without providing cross-surface aggregation. Purpose-built supply infrastructure must combine both.
How brand safety and suitability work differently inside a generated response
In legacy programmatic, suitability can begin with a known page and its category signals. In a conversation, the surrounding content is generated fresh, and the user’s circumstances may be part of its meaning. Health conditions, financial advice, and legal guidance carry heightened reputational exposure. When responses on those topics are less certain, advertisers may choose to show no ads at all. The supply layer must help enforce that choice.
A user sharing personal health concerns or financial worries is in a different relationship with the content from someone reading a general article. The conversational trajectory therefore matters to suitability. A category label alone cannot express how a discussion has developed or why a commercial message might be poorly matched.
Context-level enforcement can make suitable inventory available to advertisers who would otherwise avoid the channel. Buyers willing to pay premium CPMs for high-intent moments also need confidence in the surrounding response. Robust suitability controls support that confidence and can support better pricing than inherited page-category blocklists.
What the demand side needs from AI publisher supply, and why that shapes infrastructure requirements
Advertisers need an inventory signal they can understand, target, and trust. Context-hint targeting makes that requirement concrete because the auction must compare a buyer’s description of a suitable conversation with the conversation itself. Supply that strips away intent also strips away the basis for that comparison. Topic sensitivity and suitability metadata must accompany the intent signal so that relevance does not come at the expense of control.
Decision stage supplies another necessary distinction. B2B and SaaS buyers may prioritize explicit commercial signals including “alternatives”, “pricing”, “security”, “migration”, and “integrations”. Those queries differ from general awareness questions even when they concern the same subject. Microsoft Copilot draws on the entire session context and reports materially stronger performance than traditional search placements.
Demand also needs enough reach to justify the operational investment in a channel. Aggregating inventory across AI surfaces helps publishers participate in budgets that a single app may not attract on its own. The supply requirement is therefore both semantic and commercial. Publishers need to communicate what a moment means and place it in a market where enough relevant buyers can compete for it.
Where Thrad fits in the supply infrastructure picture for AI app publishers
Thrad runs an SSP and exchange with direct publisher supply, so it provides more than a buying platform. Its data model and bid request schema carry prompt-level intent signals, so each generated response is treated as its own commercial moment.
Its exchange layer brings each publisher’s supply to buyers across AI surfaces to meet the need for aggregation. For publishers, the relevant distinction is access to demand built to read and act on conversational context. For advertisers, the corresponding benefit is cross-surface reach without discarding intent. The combination of DSP reach and owned exchange supply connects those requirements within the same infrastructure model. It is a concrete option in a market whose broader standards are still forming.
What AI app publishers should look for when evaluating supply infrastructure today
Evaluation starts with prompt-level signal transmission. Publishers should check whether bid requests carry conversational intent in a structured form that demand can target. A page category or user segment is not an equivalent substitute. The next test is dynamic inventory definition, which requires the platform to define and price opportunities by conversation type and intent stage. Requiring fixed slots and formats leaves the foundational mismatch intact.
The third test is context-level suitability enforcement. Publishers should check that the platform evaluates the generated response or conversational trajectory for sensitivity and brand suitability, rather than applying only inherited page-category blocks. The fourth test is cross-surface demand aggregation. Access to advertisers buying across multiple AI surfaces should create genuine competitive pressure among demand sources.
The final test is attribution architecture. A measurement model must account for multi-turn conversations and delayed conversion instead of relying on last-click attribution or impression counts designed for pages. Purpose-built options remain nascent, and the market for solutions meeting all five tests is still forming. That makes evaluation important now, because early supply infrastructure choices carry a longer lock-in horizon than equivalent decisions in display or mobile app monetization.